Nemotron Lightning Is a Cheap Worker Node — Switchyard Is the Real Product
NVIDIA shipped Nemotron 3.5 Lightning, a 30B MoE with ~3B active parameters for high-volume agent execution, plus NeMo Switchyard, an open router that steers each step to the cheapest capable model. NVIDIA’s thesis is that most agent tokens are execution, not reasoning.

Corrected October 14, 2026: Removed undated Artificial Analysis scores from the summary, SEO description and checks section; corrected the LangChain partner figures (74% lower cost on 145 tasks, 7% of calls routed to a frontier model, 6% accuracy tradeoff); turned an internal reference into a link.
If agents spend most tokens on boring steps, the winning stack is frontier planner + fast open worker + router. Switchyard is strategically heavier than another small open model: it puts NVIDIA inside the decision of which model runs.
NVIDIA expanded the Nemotron 3 open family with Nemotron 3.5 Lightning — a 30-billion-parameter mixture-of-experts model with roughly 3 billion active parameters for always-on agent execution — and NeMo Switchyard, an open-source model routing library that steers each request to the right model in a developer-defined pool. NVIDIA claims ~4× throughput versus comparable in-class models at similar intelligence and up to ~30% faster completion of agentic benchmark workloads. Weights land on Hugging Face / ModelScope / OpenRouter and as NIM microservices; Switchyard is on GitHub with gateway partners including OpenRouter, LiteLLM, and Kong.
What shipped#
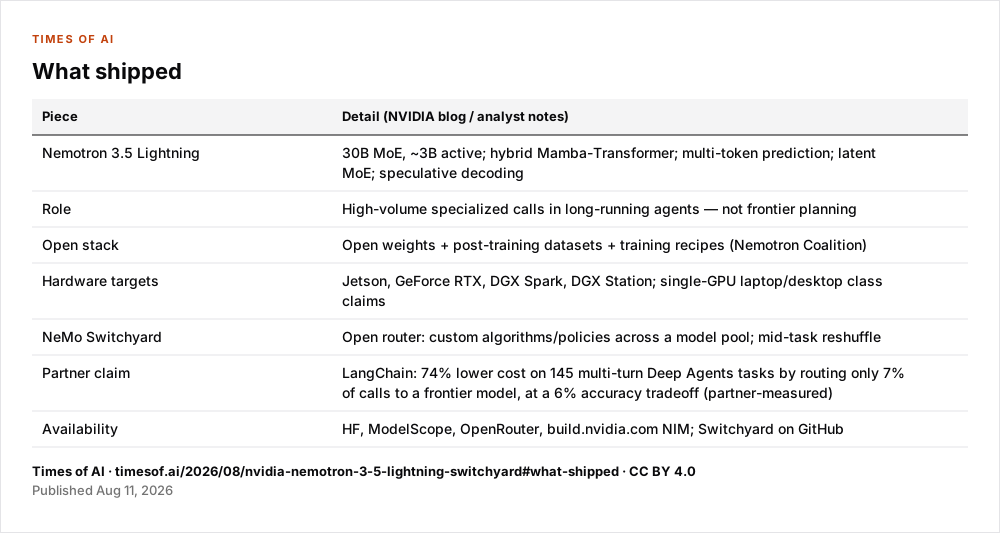
| Piece | Detail (NVIDIA blog / analyst notes) |
|---|---|
| Nemotron 3.5 Lightning | 30B MoE, ~3B active; hybrid Mamba-Transformer; multi-token prediction; latent MoE; speculative decoding |
| Role | High-volume specialized calls in long-running agents — not frontier planning |
| Open stack | Open weights + post-training datasets + training recipes (Nemotron Coalition) |
| Hardware targets | Jetson, GeForce RTX, DGX Spark, DGX Station; single-GPU laptop/desktop class claims |
| NeMo Switchyard | Open router: custom algorithms/policies across a model pool; mid-task reshuffle |
| Partner claim | LangChain: 74% lower cost on 145 multi-turn Deep Agents tasks by routing only 7% of calls to a frontier model, at a 6% accuracy tradeoff (partner-measured) |
| Availability | HF, ModelScope, OpenRouter, build.nvidia.com NIM; Switchyard on GitHub |
Claims vs checks#
Lab / partner: Throughput and agent-workload latency claims are NVIDIA’s; they are vendor benches with disclosed architecture advantages (MoE + MTP + speculative decoding).
Positioning:
- Lightning is not positioned as a Sol/Opus peer; the product is cheap reliable worker nodes behind a router.
Distinct from the $500B Wall Street financing MOUs (Aug 10) and Firebird factory open (Aug 8). Lightning + Switchyard is open model + agent infrastructure software — NVIDIA selling the orchestration layer, not only GPUs.
Limits#
- LangChain cost-reduction path is partner-measured, not an independent composite.
- Whether Switchyard becomes default in LiteLLM/Kong gateways is still open.
Sources#
- NVIDIA Blog: Nemotron 3.5 Lightning and NeMo Switchyard (August 11, 2026)
- CNBC: NVIDIA releases Nemotron 3.5 Lightning (August 11, 2026)
- The New Stack: NVIDIA Nemotron Lightning and Switchyard (August 11, 2026)
- Times of AI: NVIDIA’s $500B AI compute financing (August 10)
- Hugging Face: nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 model card