Inkling-Small: 12B Active Beats Full Inkling on Coding—Lab Tables, Open Weights
Thinking Machines released Inkling-Small (276B/12B active open MoE) claiming SWE-Bench Verified 80.2% and ARC-AGI-2 40.1%—ahead of full Inkling—with vendor-cited output pricing of $1.20 per million tokens. Efficiency play for US open weights; treat coding wins as lab-reported without implying independent replication.

Open-weight labs are racing on performance-per-active-parameter, not only total-parameter headlines. Beating a 975B sibling on coding with 12B active is a sharp efficiency signal—and a direct answer to Chinese open MoE cost pressure.
Thinking Machines Lab released Inkling-Small as full open weights—the efficient sibling previewed with Inkling on July 15. Specs: 276B total / 12B active MoE, native multimodal (text, images, audio), up to 1M context, variable thinking effort. Lab claims it beats full Inkling on agentic coding (SWE-Bench Verified 80.2% vs 77.6%) and ARC-AGI-2 (40.1% vs 36.5%) while lagging on factual recall (SimpleQA 20.6% vs 43.9%). The launch’s cost comparison uses $1.20 per million output tokens, against $4.05 for Inkling. Weights on Hugging Face; fine-tune/chat on Tinker.
What Inkling-Small is#
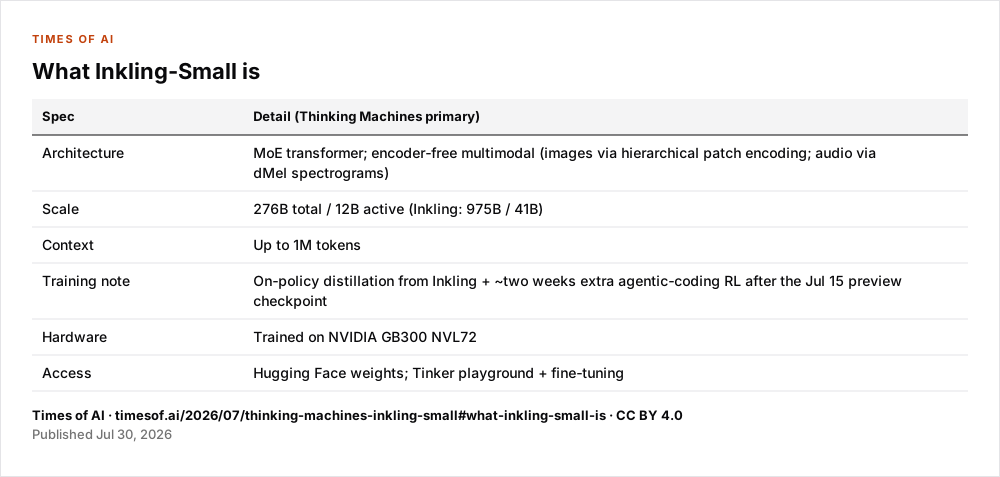
| Spec | Detail (Thinking Machines primary) |
|---|---|
| Architecture | MoE transformer; encoder-free multimodal (images via hierarchical patch encoding; audio via dMel spectrograms) |
| Scale | 276B total / 12B active (Inkling: 975B / 41B) |
| Context | Up to 1M tokens |
| Training note | On-policy distillation from Inkling + ~two weeks extra agentic-coding RL after the Jul 15 preview checkpoint |
| Hardware | Trained on NVIDIA GB300 NVL72 |
| Access | Hugging Face weights; Tinker playground + fine-tuning |
Selected lab benchmarks (effort 0.99, temperature 1; primary tables)#
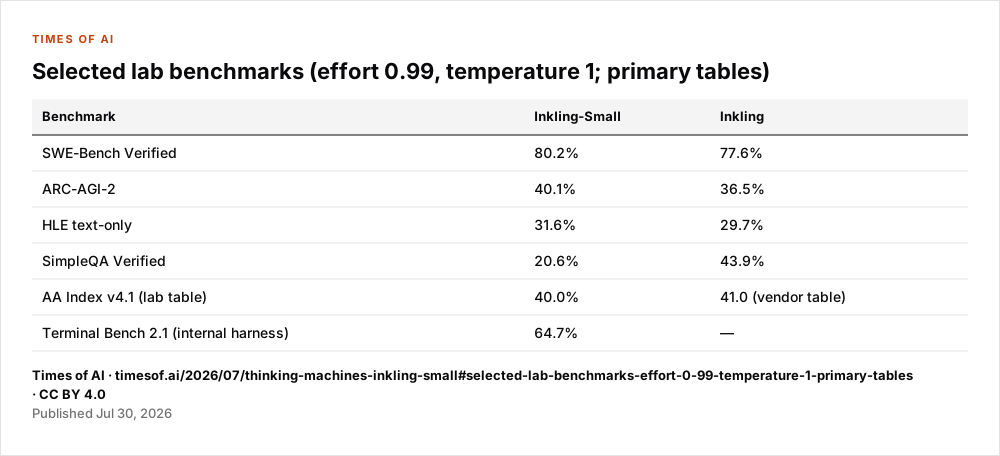
| Benchmark | Inkling-Small | Inkling |
|---|---|---|
| SWE-Bench Verified | 80.2% | 77.6% |
| ARC-AGI-2 | 40.1% | 36.5% |
| HLE text-only | 31.6% | 29.7% |
| SimpleQA Verified | 20.6% | 43.9% |
| AA Index v4.1 (lab table) | 40.0% | 41.0 (vendor table) |
| Terminal Bench 2.1 (internal harness) | 64.7% | — |
Safety: StrongREJECT 98.4%; FORTRESS adversarial 71.6% / benign 96.9% at effort 0.99 (primary table).
Claims vs checks#
The benchmark figures above are vendor model-card results. The card’s AA Index row is not an independent, dated AA placement, and this article does not establish a historical Arena rank. The smaller model’s coding and reasoning gains sit alongside a substantial SimpleQA Verified regression against Inkling.
Inkling-Small is a new product-line tier from the same lab: a small open MoE optimized for coding/agent cost curves.
Limits#
- Coding and ARC wins are vendor tables; no independent launch ranking is established here.
- SimpleQA regression (20.6% vs 43.9%) is the honest factuality trade.
- Terminal Bench figure uses an internal harness.
Correction (October 14, 2026): Removed unverified input pricing, launch-infrastructure and historical ranking claims; retained vendor benchmarks with their source and caveats.