Record
Lab claims and independent checks
Rows are added when we publish a launch article that cites a lab claim, and a row changes when a published article records a new check. Last updated Oct 27, 2026.
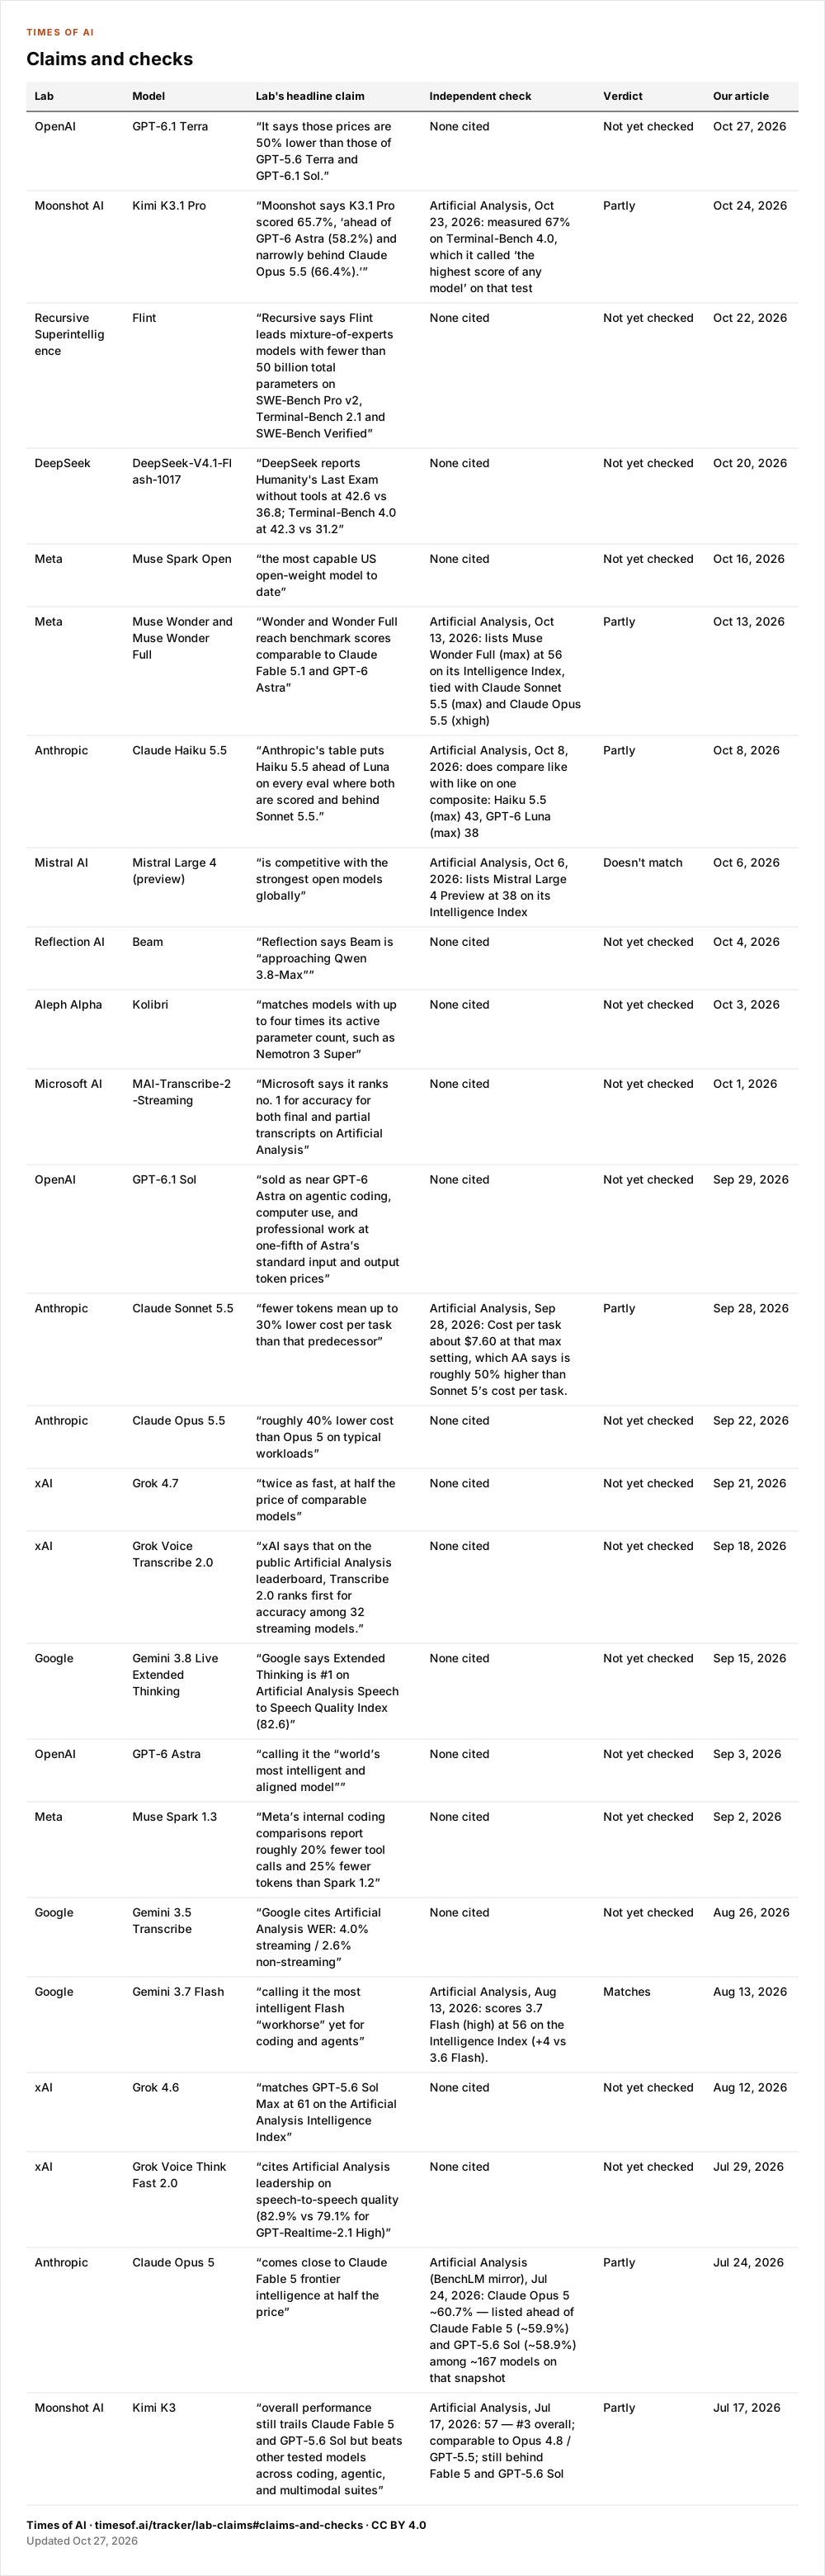
Each row is one model launch: the lab's headline claim, the independent check one of our articles cites for it, and a plain verdict. Every claim, check, date and link here comes from an article we have already published. Where an article cites no independent check, the row says so.
Claims and checks#
What the verdicts mean#
- Matches. The independent figure for the same measure agrees with the claim, as the article reads it.
- Partly. The check supports only part of the claim, was run at a different setting, or the article reads it both ways.
- Doesn't match. The independent figure for the same measure disagrees with the claim, as the article reads it.
- Not yet checked. The article cites no independent check of this claim.
Notes on each verdict#
- GPT-6.1 Terra. Our article compares the price with two earlier Times of AI reports and finds the output price about 58% lower than GPT-5.6 Terra's, not 50%. It cannot say why. That is our arithmetic, not an independent check. The Artificial Analysis page it cites covers other measures.
- Kimi K3.1 Pro. AA's 67% is above Moonshot's 65.7%, and AA calls it the highest of any model where Moonshot's table has it narrowly behind Opus 5.5. The article says AA tested the API model, which may differ from the open-weight version. It cites several AA posts and does not say which one carries this figure.
- Flint. The article records that Artificial Analysis's leaderboard did not list Flint when checked at 02:59 UTC on October 22. That is an absence, not a score, so there is no check to cite.
- DeepSeek-V4.1-Flash-1017. Artificial Analysis scored the model 45.10 on its Intelligence Index, a different measure. The article says only that index is independent here.
- Muse Spark Open. The article calls this Meta's claim. The Artificial Analysis score it prints (39) comes from Meta's own comparison table and sits beside non-US models, so it does not test the claim.
- Muse Wonder and Muse Wonder Full. AA puts Wonder Full two points below the top entry, so it is close. The article calls it the only non-Anthropic model in AA's top four, but gives no AA scores for Fable 5.1 or Astra, so the comparison named in the claim is not shown directly.
- Claude Haiku 5.5. AA agrees with the direction on one composite at max effort. The article calls Anthropic's table not like-for-like, because the effort levels behind the Luna column are unclear. Haiku's own Terminal-Bench score falls from about 39% at max to about 20% at the default medium setting.
- Mistral Large 4 (preview). On AA's index the preview sat well behind the top open models (MiMo-V2.6-Pro 46, GLM-5.3 45, Kimi K3 44). The article says that is not a verdict on the final checkpoint. Mistral's claim also says the model outperforms any U.S. or European open-weight model, which nothing cited tests.
- Beam. The article says every benchmark is vendor-reported, the comparison table is vendor-compiled, and TechCrunch notes the claims are not independently verified.
- Kolibri. The article calls this Aleph Alpha's own comparison, not an independent audit. A look at the Artificial Analysis and LM Arena boards on the evening of October 4 did not show the model, which the article says is not a quality verdict.
- MAI-Transcribe-2-Streaming. Our article saw Artificial Analysis's result only via a 24/7 Wall St. card; not yet confirmed on Artificial Analysis directly.
- GPT-6.1 Sol. The article found no third-party leaderboard result for the model on launch day and says “near Astra” rested on OpenAI's own task-level cost curves.
- Claude Sonnet 5.5. AA's cost per task, about 50% higher than Sonnet 5's at max effort, points the other way. The article says the two figures are at different effort points and task baskets, so they are not directly comparable. It also notes AA's Terminal-Bench 4.0 run was 64%, not Anthropic's 70.6%, and leaves that gap unresolved.
- Claude Opus 5.5. The article adds later Artificial Analysis and Andon Labs checks. They measure an intelligence index and simulated vending profit, not this cost claim.
- Grok 4.7. The only independent check the article cites is Andon Labs's Vending-Bench 2, a different measure from this price and speed claim. It says it establishes no Arena or Artificial Analysis score for the model.
- Grok Voice Transcribe 2.0. The article attributes the ranking to xAI's account of Artificial Analysis and says it did not verify the live board.
- Gemini 3.8 Live Extended Thinking. The article lists the ranking under benchmarks as reported by Google. A correction on October 14 attributed it to Google and did not replace it with a check of the board.
- GPT-6 Astra. The article lists the lab's benchmarks as vendor-reported and says an independent LMArena or Artificial Analysis ranking is not verified.
- Muse Spark 1.3. Artificial Analysis's September 2 evaluation measured its Intelligence Index and cost per task, which the article says are separate from Meta's coding-efficiency tests.
- Gemini 3.5 Transcribe. The article calls the Artificial Analysis score the independent score Google cites, and says it did not inspect the original scorecard.
- Gemini 3.7 Flash. The article reads AA's +4 over Gemini 3.6 Flash as supporting the capability claim. It does not test Google's own coding and agent figures.
- Grok 4.6. The article attributes the table to xAI and says no separately inspected Artificial Analysis or Arena snapshot is claimed.
- Grok Voice Think Fast 2.0. The article lists the Artificial Analysis figure as cited on xAI's launch post. It links the board but gives no reading of it.
- Claude Opus 5. The snapshot lists Opus 5 slightly ahead of Fable 5, which fits "comes close". It is a July 24 reading through a third-party mirror of AA's index, and the article says to treat it as dated. It does not test the half-price part of the claim.
- Kimi K3. AA ranks K3 third overall, behind Fable 5 and GPT-5.6 Sol, which fits the first half of Moonshot's claim. AA calls it comparable to Opus 4.8 and GPT-5.5 rather than ahead of them, and the check covers one index, not the coding, agentic and multimodal suites Moonshot cites.
Limits#
- A verdict reflects only the check the article cites, at the setting and date it gives. Benchmark pages change, and a later check can differ.
- A check often measures something other than what the lab claimed. The notes say when it does.
- Verdicts are our reading of our own articles. They are not a ruling by the lab or by the checker, and a missing check is not evidence either way.