Qwen3.8-Flash-Next Releases Open Weights for a Qwen4 Architecture Preview
Qwen3.8-Flash-Next has a 125B backbone with 6B active parameters, plus 51B n-gram embeddings and 4B MTP parameters. Its official model card describes a multimodal Qwen4 architecture preview with 262K native context and vendor benchmark results.

Qwen3.8-Flash-Next previews a new architecture for Qwen4 with publicly available weights. The benchmark numbers below come from Qwen’s model card, not an independent leaderboard snapshot.
Alibaba Qwen released Qwen3.8-Flash-Next weights, available on its official Hugging Face repository. Architecture: 125B backbone + 51B N-gram embeddings + 4B MTP; 6B active per token; 262K native context, 1M with YaRN. Vendor benches: DeepSWE 1.1 58.7, SWE-bench Pro 62.5, CoWorkBench 73.9, LiveCodeBench v6 91.9, GPQA Diamond 91.7. The model card distinguishes the weights from the managed Qwen3.8-Flash API, which has additional production features. Qwen frames it as a Qwen4 architecture preview.
What shipped#
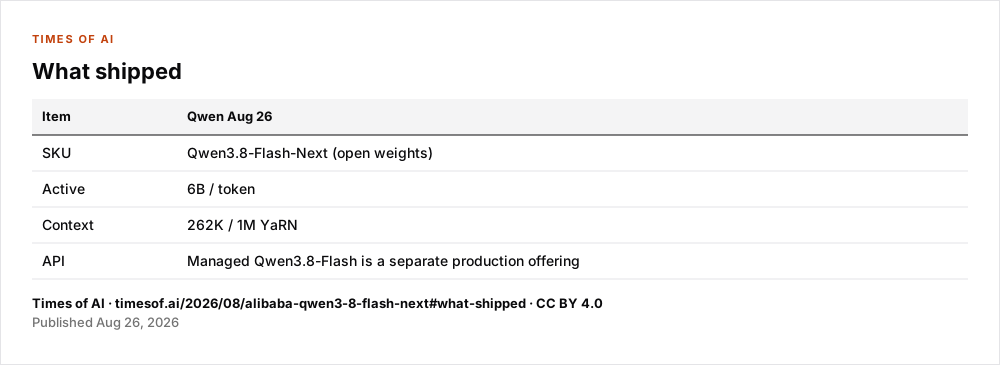
| Item | Qwen Aug 26 |
|---|---|
| SKU | Qwen3.8-Flash-Next (open weights) |
| Active | 6B / token |
| Context | 262K / 1M YaRN |
| API | Managed Qwen3.8-Flash is a separate production offering |
The current repository lists the Qwen Community 1.0 license. Public weights should not be described as unrestricted open source.
Limits#
- The listed benchmark results are Qwen’s evaluations; this article does not establish a historical independent ranking.
- DeepSWE uses the higher result across two harnesses; CoWorkBench is Qwen’s in-house benchmark.
- The current API page is not a historical August 26 pricing snapshot.
Correction (October 14, 2026): Added the official model card, clarified additional embedding/MTP parameters and open-weight licensing, and removed an unverified training-cost ratio and historical API price. Current pricing cannot establish the launch-day price.